Summarize this article with:
Thinking Machines' Inkling 2 Small scores like Gemini 3.8 Flash at a fraction of the cost per task, but it uses 4x more tokens than its predecessor. What it does well, what it really costs and when you can run it.
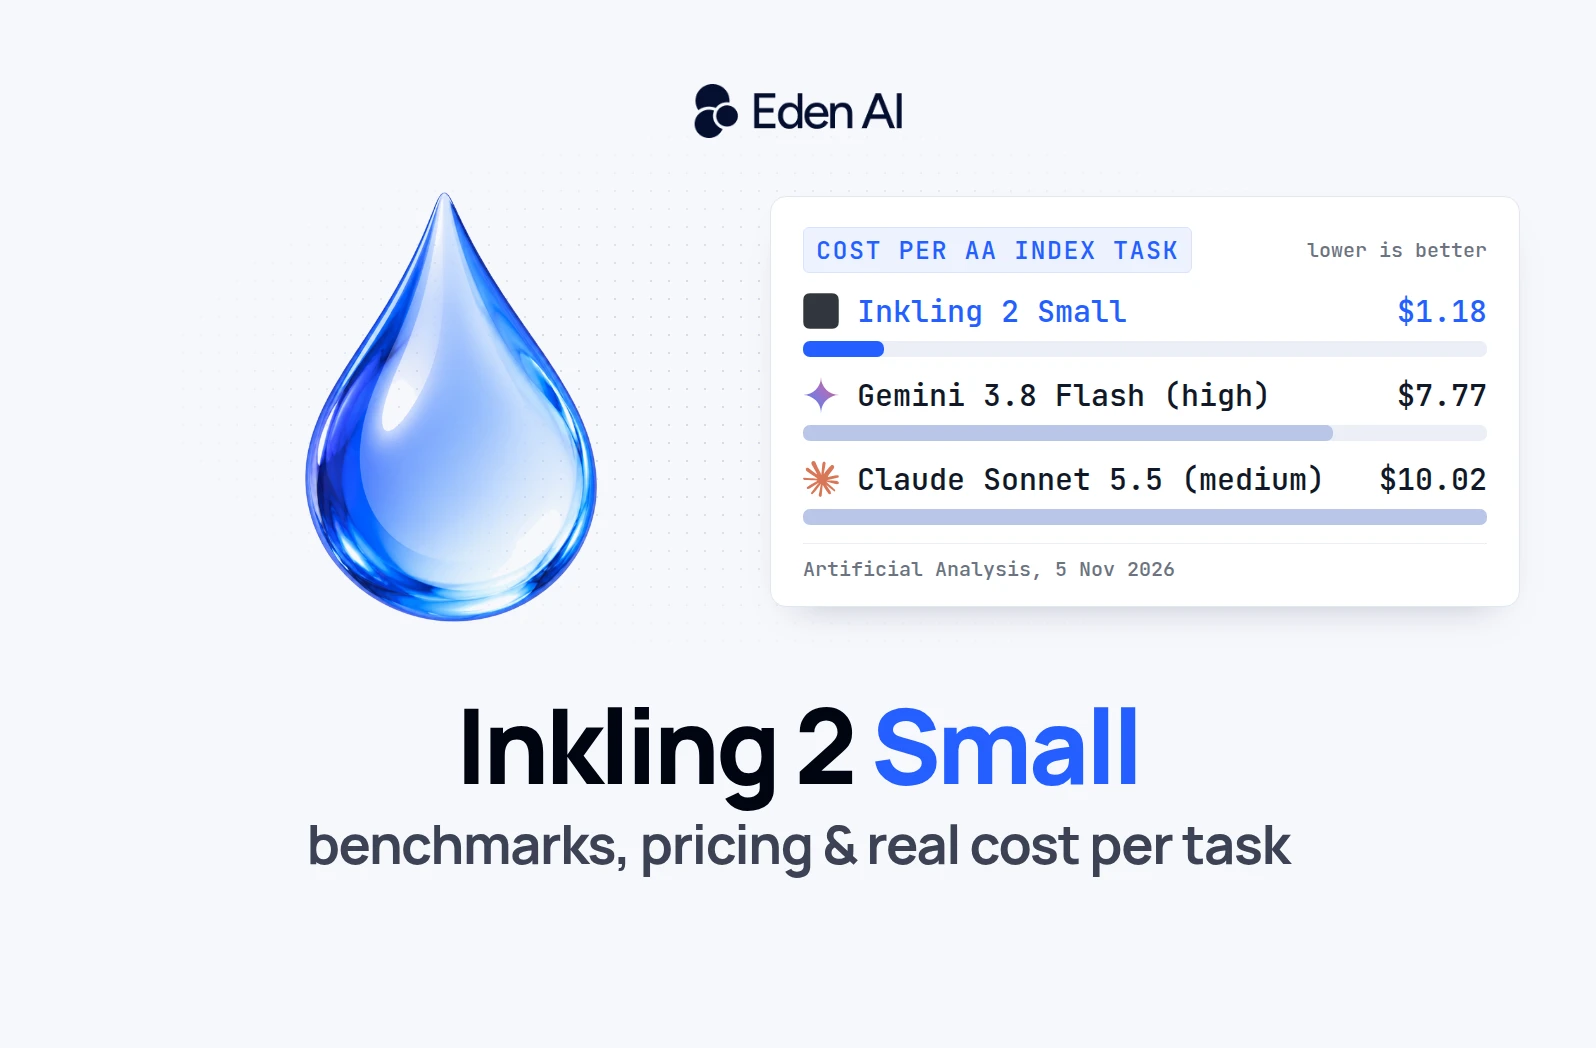
Short answer: about $1.18 per task, according to Artificial Analysis. That is roughly a sixth of what Gemini 3.8 Flash costs for the same score, and almost six times what its little brother Inkling Small costs, because the new model likes to think out loud: about 150,000 output tokens per task. Cheap tokens, chatty model.
Inkling 2 Small was released on 5 November 2026 by Thinking Machines Lab, the company founded by former OpenAI CTO Mira Murati. It is a mixture-of-experts model with 594 billion parameters, of which 17 billion are active for each token, and it reads both text and images. It scores 31 on the Artificial Analysis Intelligence Index, level with Gemini 3.8 Flash (high), well ahead of the first Inkling Small. The catch: it only runs on Thinking Machines' own platform for now, and its weights are still to come.
This guide covers what the model does well, where it falls short, what a task really costs, and how to prepare your stack so that trying it takes one line of code.
Inkling 2 Small at a glance
| Released | 5 November 2026, by Thinking Machines Lab |
| Architecture | Mixture of experts, 594B total parameters, 17B active |
| Input and output | Text and image in, text out. Context window up to 1M tokens. Adjustable reasoning effort |
| AA Intelligence Index | 31, up 18 points from Inkling Small, level with Gemini 3.8 Flash (high) |
| Price on Tinker | $0.30 input, $0.03 cached input, $1.00 output, per 1M tokens |
| Access today | Tinker only: Playground, inference API and fine-tuning |
| Weights | Apache 2.0, announced for the week after launch, after external safety testing. No confirmed date yet |
| On Eden AI | Not yet. Inkling and Inkling Small are available now |
What changes compared with Inkling Small
Inkling 2 Small is a new model trained from scratch, not an update of the first generation. Thinking Machines highlights four changes.
- A bigger "small" model: Inkling Small had 12 billion active parameters out of 276 billion. Inkling 2 Small has 17 billion active, out of 594 billion in total.
- Long agentic work: it was trained with reinforcement learning on hundreds of thousands of long coding tasks, graded on how the model worked and not only on whether tests passed. On Artificial Analysis' AutomationBench, it goes from 5% to 46%.
- Vision in the loop: a 292M-parameter vision encoder lets it read screenshots, charts and documents, and check its own visual output while it builds websites or 3D scenes.
- Built to be fine-tuned: on a financial analysis task, it reached the final score of Inkling Small after just 75 training steps, and kept improving.
The training itself was frugal by current standards. Pre-training covered about 12.6 trillion tokens in four phases, the first one in 68 hours, and the main reinforcement learning run took 9 days on 2,048 GPUs. As Stéphane Requena, CTO of the French supercomputing agency GENCI, pointed out, that is much less compute and data than the models it competes with.
Benchmarks: where it wins and where it doesn't
Thinking Machines compares Inkling 2 Small with the strongest open-weight models of similar size. Here is a selection of its table.
| Category | Benchmark | Inkling 2 Small | DeepSeek V4.1 Flash | Kimi K3 | GLM-5.3-Flash |
|---|---|---|---|---|---|
| Coding | DeepSWE v1.1 | 72.1% | 77.0% | 68.5% | 63.4% |
| Coding | Vibe Code Bench v1.1 | 81.6% | 87.7% | 85.0% | 30.8% |
| Vision | MMMU Pro | 81.6% | 80.6% | 80.5% | 79.0% |
| Vision | ScreenSpot Pro | 83.8% | not reported | 73.8% | not reported |
| Finance | Vals Finance Index | 61.5% | 60.9% | 58.0% | 55.8% |
| Legal | Vals Legal Index | 73.9% | 71.9% | 71.7% | 71.1% |
| Knowledge work | AA-Briefcase v1.1 (Elo) | 1527 | 1570 | 1497 | 1451 |
| Reasoning | HLE-Diamond | 28.7% | not reported | 26.9% | 18.2% |
Three things stand out:
- Vision and documents are its strongest area. It leads on MMMU Pro and ScreenSpot Pro, and is set to be the top open-weight model on DesignArena's website leaderboard once its weights are out.
- Finance and legal work come next. It is the best open-weight model in the table on the Vals Finance and Legal indexes, which test reasoning over filings, spreadsheets and contracts.
- Coding is good, not best. DeepSeek V4.1 Flash stays ahead on DeepSWE and Vibe Code Bench, and Kimi K3 on SWE-Bench Pro. Artificial Analysis also notes that Inkling 2 Small scores 13% on Terminal-Bench 4.0, against 30% for Claude Sonnet 5.5.
Most of these figures come from Thinking Machines. Independent results from Artificial Analysis confirm the overall level, with one nuance: hallucinations fall from 61% to 27% mainly because the model declines to answer more often, while accuracy only rises from 32% to 34%.
Price per token is not cost per task
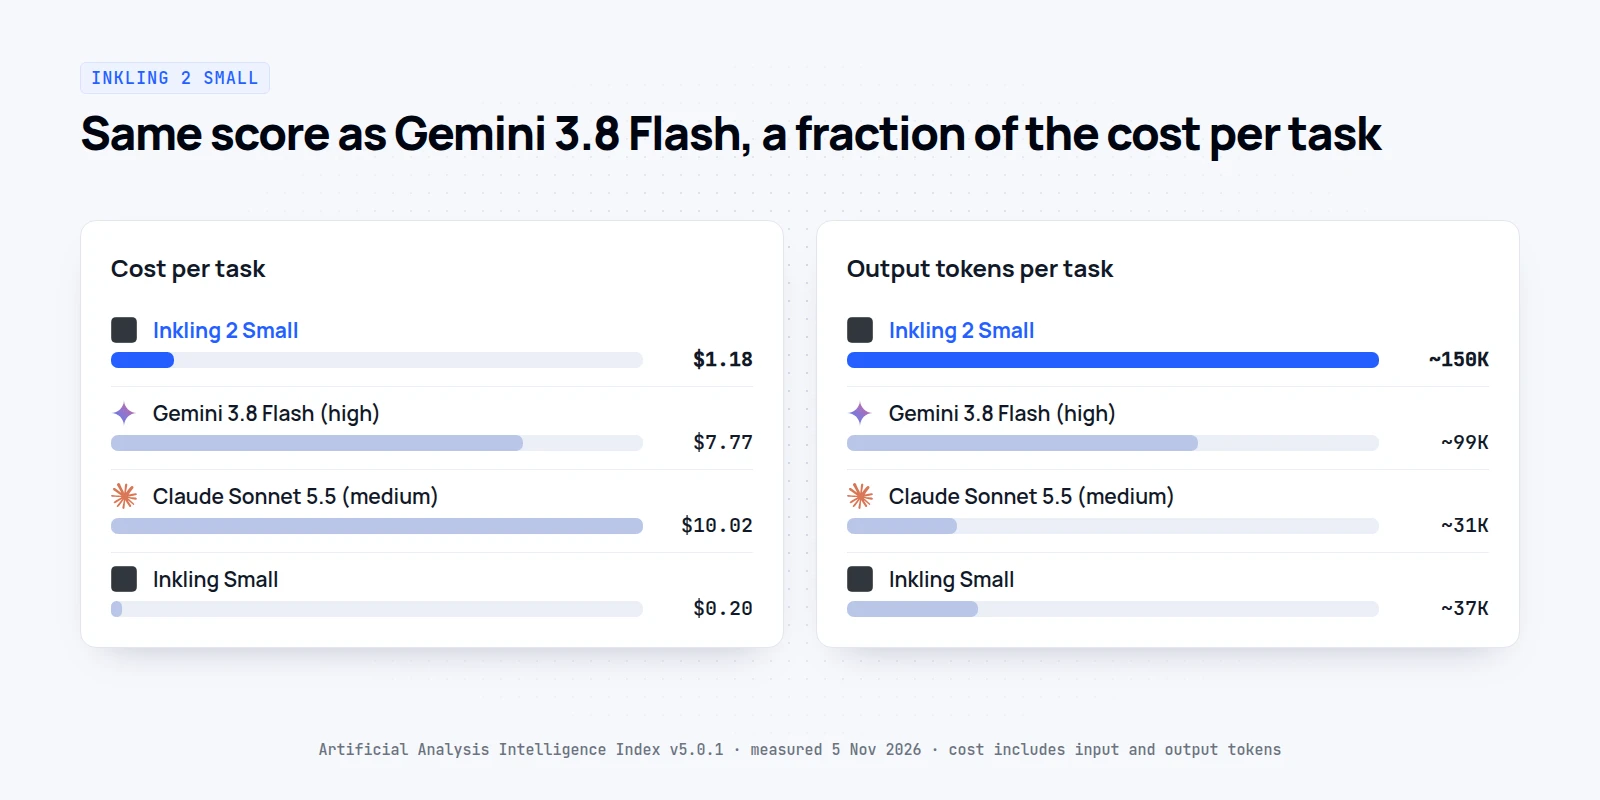
At $0.30 per million input tokens and $1.00 per million output tokens, Inkling 2 Small is one of the cheapest models at its level. But a token price only tells half the story: what you pay is the price multiplied by the number of tokens the model spends to finish the job. Artificial Analysis measures both.
| Model | Price per 1M tokens (input / output) | Output tokens per task | Cost per task |
|---|---|---|---|
| Inkling 2 Small | $0.30 / $1.00 (Tinker) | ~150K | $1.18 |
| Gemini 3.8 Flash (high) | $0.75 / $3.75 | ~99K | $7.77 |
| Claude Sonnet 5.5 (medium) | $2.00 / $10.00 | ~31K | $10.02 |
| Inkling Small | $0.45 / $1.20 (DeepInfra) | ~37K | $0.20 |
Two lessons come out of this table:
- Against models of the same level, it is far cheaper. For the same Intelligence Index score, a task costs about 6.6 times less than with Gemini 3.8 Flash (high), and 8.5 times less than with Claude Sonnet 5.5 (medium), even though it writes more.
- Against its predecessor, it costs almost 6 times more per task. Inkling 2 Small thinks longer: about 150,000 output tokens per task, four times Inkling Small. You get a much better answer, but you pay for every extra token.
In practice, the cost of a model depends on your tasks, not on its price list. A short classification will cost almost nothing with any of these models, while a long agent run can multiply the bill. Thinking Machines trained Inkling 2 Small with several effort levels and a length penalty, so lowering the effort on simple requests is the first lever to keep its token use in check.
Closed today, Apache 2.0 soon
For now, Inkling 2 Small runs only on Tinker, Thinking Machines' platform, where you can try it in the Playground, call it through an API or fine-tune it. Thinking Machines follows what it calls a safe path to open weights: it announced the weights under the Apache 2.0 license for the week after launch, once external safety testing and red-teaming are complete. Artificial Analysis lists the date as unconfirmed.
Once the weights are out, three things change:
- More places to run it: inference providers can host it, as they did with Inkling and Inkling Small, which are both served on Eden AI today.
- Self-hosting becomes possible: with 594 billion parameters, the full model needs a multi-GPU server, even if only 17 billion are active per token.
- Fine-tuned checkpoints become portable: models customised on Tinker will be downloadable.
Artificial Analysis expects it to become the highest-scoring open-weight model developed outside China at that point.
Which model for which task
Inkling 2 Small is not a default for everything. Based on the published results, here is where it fits.
- Documents, screenshots and charts: this is its strongest area, with a vision encoder and the best MMMU Pro and ScreenSpot Pro scores in its group.
- Finance and legal analysis: it leads the open-weight models on the Vals Finance and Legal indexes, and it is designed to be fine-tuned on your own data.
- Agentic coding: DeepSeek V4.1 Flash and Kimi K3 remain stronger on most coding benchmarks, and DeepSeek V4.1 Flash costs less than $0.10 per million input tokens and $0.40 per million output tokens on Eden AI.
- Short, high-volume requests: a smaller model is usually enough, and the price-performance routing approach keeps the expensive models for the requests that need them.
How to get ready with Eden AI
Inkling 2 Small is not on Eden AI yet, because it is only served on Tinker. Its two predecessors, Inkling Small and Inkling, are available now, along with DeepSeek, Kimi, Gemini, Claude and GPT models, behind one API key and one OpenAI-compatible endpoint. When a provider we work with serves Inkling 2 Small, adding it will be a change of model name.
The best preparation is to measure what a task really costs you today, with the same prompt across several models:
from openai import OpenAI

client = OpenAI(api_key="YOUR_EDENAI_API_KEY", base_url="https://api.edenai.run/v3")

task = (
    "Read this quarterly result and list the three main risks: "
    "revenue +4%, gross margin -3 pts, inventory +22%, cash -15%."
)

# add Inkling 2 Small to this list when a provider serves it
for model in [
    "deepinfra/thinkingmachines/Inkling-Small",
    "google/gemini-3.8-flash",
    "deepinfra/deepseek-ai/DeepSeek-V4.1-Flash-1017",
]:
    response = client.chat.completions.create(
        model=model,
        messages=[{"role": "user", "content": task}],
    )
    tokens = response.usage.completion_tokens
    cost = getattr(response, "cost", 0)  # Eden AI returns the cost of each call
    print(f"{model}: {tokens} output tokens, ${cost:.4f}")
We ran this on 9 November 2026. For the same prompt, DeepSeek V4.1 Flash answered in 108 output tokens for less than $0.0001, Inkling Small in 696 tokens for about $0.0009, and Gemini 3.8 Flash in 599 tokens for about $0.0023. Same task, a 6x gap in tokens and a 30x gap in cost: that is what the price list does not tell you.
Once you have picked a model, Eden AI handles the production side:
- One bill and one key for every model, so testing a new one never starts with a new contract.
- Fallbacks to another model or provider when one fails, set in the same request.
- Provider routing to sort providers by price or set your own order, when the same model is served by several of them.
What to keep in mind
- Most benchmarks are Thinking Machines' own: Artificial Analysis confirms the overall level, but test on your own tasks before switching.
- No firm date for the weights: Thinking Machines said "next week" on 5 November, after safety testing. Do not plan a migration around it yet.
- It spends a lot of tokens: about 150,000 output tokens per task on the Intelligence Index. Watch your token use and set the effort level to match the task.
- Tinker prices are not the final word: once providers host the model, prices will depend on each of them.
FAQ
What is Inkling 2 Small?
Inkling 2 Small is a multimodal model from Thinking Machines Lab, released on 5 November 2026. It is a mixture-of-experts model with 594 billion parameters, 17 billion of them active, that takes text and images as input and returns text. It scores 31 on the Artificial Analysis Intelligence Index.
How much does Inkling 2 Small cost?
On Tinker, $0.30 per million input tokens, $0.03 for cached input and $1.00 per million output tokens. Artificial Analysis measured an average cost of $1.18 per Intelligence Index task, against $7.77 for Gemini 3.8 Flash (high).
Is Inkling 2 Small open source?
Not yet. It launched with closed weights on Tinker. Thinking Machines plans to release the weights under the Apache 2.0 license after external safety testing, and announced it for the week after launch.
Is Inkling 2 Small better than Inkling Small?
Yes, by a wide margin: 31 on the Artificial Analysis Intelligence Index against 13, with large gains on agentic tasks, vision and reasoning. It also uses about four times as many output tokens per task, so it costs more to run.
Is Inkling 2 Small available on Eden AI?
Not yet, because it is only served on Tinker for now. Inkling and Inkling Small are available on Eden AI today. When a provider serves Inkling 2 Small, it can be added to the catalogue and called with the same API.